


Overview
Parsing structured text streams and mining operational metrics from massive server logs represent core daily responsibilities for Linux administrators. The GNU cut utility remains one of the fastest and most dependable command-line tools for slicing tabular data. This hands-on walkthrough covers foundational and advanced flags—including custom delimiters, selective field targeting, fixed-width byte offsets, and complementary filtering—tested directly on Ubuntu.
Setting Up the Sandbox Environment and Test Datasets
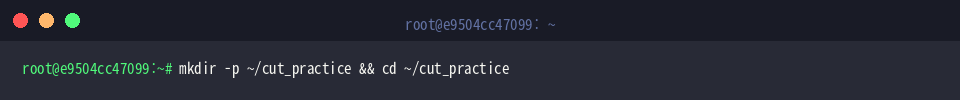
To ensure an isolated workspace without cluttering your home directory, create a dedicated scratch folder and navigate into it using mkdir -p ~/cut_practice && cd ~/cut_practice.
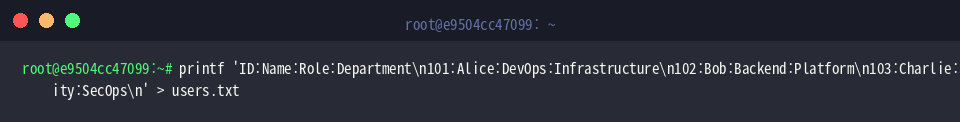
Next, generate a colon-delimited dataset resembling system password records or flat inventory tables by executing the following printf command to write users.txt.
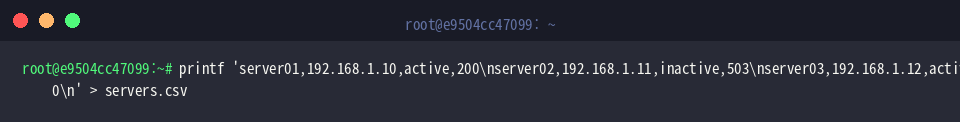
To explore comma-separated parsing scenarios, build a mock server health report saved as servers.csv via printf.
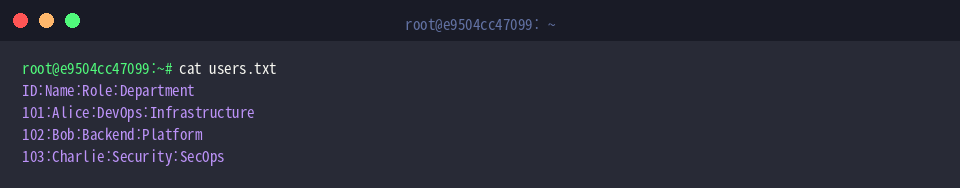
Inspect the contents of users.txt with cat users.txt to confirm that the column headers and mock employee records follow the expected colon-separated layout.
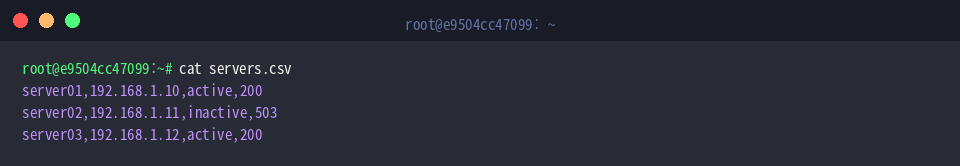
Similarly, run cat servers.csv to ensure that server hostnames, IP addresses, node statuses, and HTTP response codes populated properly.
Isolating Columns with Delimiters (-d) and Field Selectors (-f)
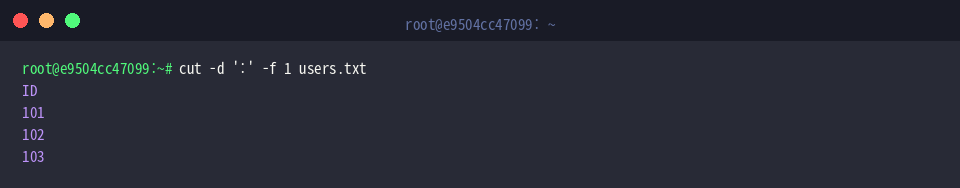
When working with delimiter-separated files, the -d parameter identifies the boundary character, while -f pinpoints which column indices to retain. Pulling just the user identifiers from users.txt is accomplished with cut -d ':' -f 1 users.txt.
Here, specifying -d ':' tells the parser to split records at colons, and passing -f 1 grabs only the leading field while discarding remaining attributes.
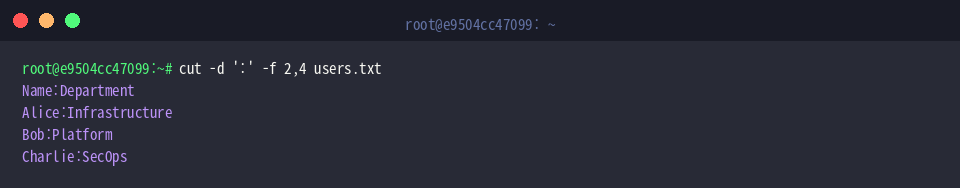
To pick multiple non-consecutive fields across records, provide a comma-delimited index list: cut -d ':' -f 2,4 users.txt.
This invocation filters out all metadata except the employee names (index 2) and organizational departments (index 4), outputting them joined by the original delimiter.
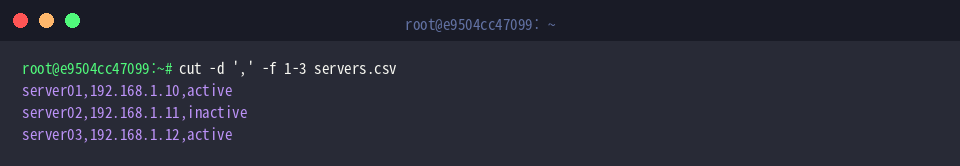
When extracting consecutive series of attributes, hyphenated index ranges simplify the query: cut -d ',' -f 1-3 servers.csv.
By setting -d ',' for comma handling alongside -f 1-3, you selectively grab the hostnames, internal IPs, and operating statuses while omitting the final status codes.
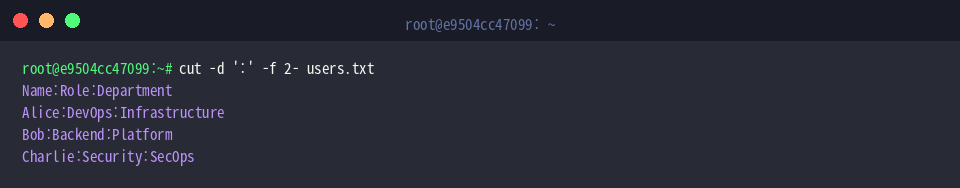
Open-ended ranges let you grab everything from a baseline index through the tail of the line, as seen in cut -d ':' -f 2- users.txt.
Using -f 2- instructs the utility to prune the numeric identifier column while printing the remaining fields intact.
Slicing Fixed-Width Streams by Character (-c) and Byte (-b) Offsets
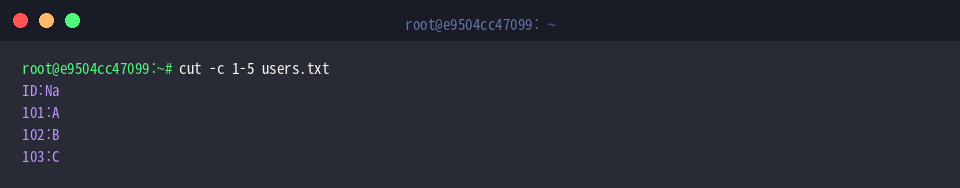
Unlike delimited text, mainframe exports or fixed-width log streams require positional slicing regardless of token boundaries. To carve out the first five characters of every record, execute cut -c 1-5 users.txt.
The -c 1-5 flag scans directly by character count, producing a uniform five-character window from the head of each line.
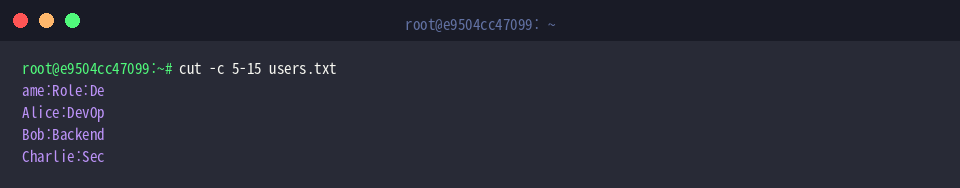
Arbitrary mid-string segments can be targeted by specifying specific start and end indices: cut -c 5-15 users.txt.
Passing -c 5-15 isolates the exact span spanning positions 5 through 15 across all rows.
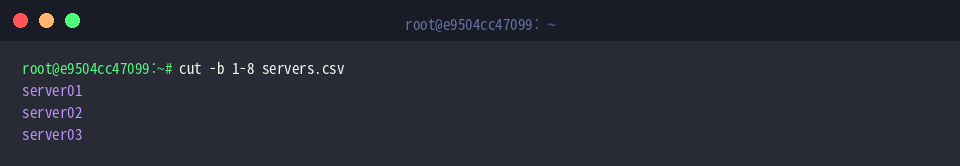
When handling binary streams or pure ASCII data where raw memory offsets matter, byte-level slicing proves optimal: cut -b 1-8 servers.csv.
Configuring -b 1-8 reads bytes 1 through 8 directly, isolating the fixed-length machine names without invoking multibyte character parsing logic.
Advanced Formatting: Modifying Output Delimiters and Inverting Fields
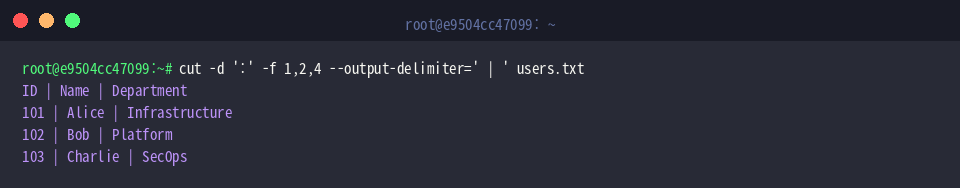
By default, cut preserves the input separator in its output. To reshape the extracted data for clearer presentation, use cut -d ':' -f 1,2,4 --output-delimiter=' | ' users.txt.
The --output-delimiter=' | ' argument transforms the original colon markers into spaced pipe characters, creating clean, visually distinct tabular reports in the terminal.
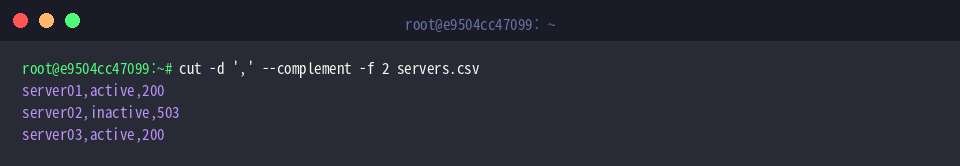
When you need to prune a sensitive column (such as an internal IP) while keeping everything else intact, field inversion is ideal: cut -d ',' --complement -f 2 servers.csv.
Adding --complement reverses field selection logic—instead of retaining column 2, the command drops it and outputs fields 1, 3, and 4.
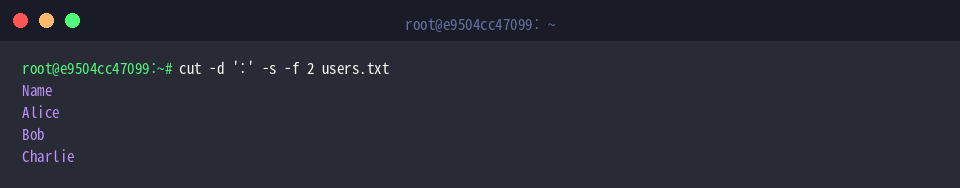
Unstructured headers, comments, or blank lines lacking delimiters can pollute parsed output. To suppress non-matching lines automatically, run cut -d ':' -s -f 2 users.txt.
The -s (or --only-delimited) modifier instructs cut to skip any record missing the designated delimiter, guaranteeing that only syntactically valid rows produce field extractions.
Understanding these operational switches equips you to streamline shell scripts, manipulate CSV exports, and quickly dissect multi-gigabyte log archives directly from the Linux terminal. Integrating cut into your daily CLI toolkit significantly accelerates data hygiene and processing pipelines on Ubuntu systems.